Today we are introducing the Apache Ossie integration in Cube.
You can now convert a Cube data model to Apache Ossie and back. Export turns your model, or a single view, into one Ossie file. Import takes an Ossie model and gives you Cube YAML, a set of cubes with a view on top, which you review, commit, and deploy like any other change to your model. Both work from the Cube CLI and the Platform API.
Both directions run on the open-source Cube ⇄ Ossie converter in the Apache Ossie repository. In this post I'll explain what Ossie is, walk through exporting your first model, and then show how the conversion works, including join fan-out, where a straight translation would give you wrong numbers.
What Apache Ossie is
Every BI tool and semantic layer keeps its model in its own format, and that model takes a lot of work to get right. It holds what counts as revenue, which tables join on which keys, how an active user is defined, and these days also the instructions and synonyms an AI agent needs to answer questions correctly. When a company moves to a new tool, someone usually rewrites all of it by hand and then spends weeks working out why the totals don't match.
Apache Ossie (it used to be called OSI, Open Semantic Interchange) is an open, vendor-neutral standard for that model. Snowflake started it in September 2025 together with a group of data and analytics vendors, the first version of the spec came out in January, and this summer it became an Apache project. Instead of every pair of tools needing its own converter, each vendor writes one converter to and from Ossie.
An Ossie model is a YAML file. It has datasets (tables or SQL queries, with their fields and keys), relationships between them, metrics, AI context for agents, and custom extensions, where each vendor keeps whatever the spec doesn't cover.
For Cube users this means two things. If your model already lives in a tool that writes Ossie, you can bring it into Cube without rebuilding it by hand. And the model you build in Cube isn't locked in: you can get it out in an open format whenever you want.
Ossie is a file format, not a semantic layer. It doesn't run queries, cache results, or apply access control. Cube is still where the model lives and runs, so a model you import becomes a regular Cube data model, and Analytics Chat, workbooks, dashboards, embedded analytics, and the APIs query it like any other.
Cube's part
Cube has been involved from the start. We were a launch partner when Snowflake announced the project in September 2025 (our post from back then), and we've been in the working group ever since. Pavel Tiunov, our CTO, works on the Expression Language part of the spec, which defines the SQL that metrics and fields are written in.
I wrote the official Cube converter in the Apache repo. It was merged in September, and it's what import and export in Cube run on.
Getting started
Say you already have a data model in Cube and you want it as an Ossie file.
1. Install the Cube CLI and log in. The cube ossie commands are in Cube CLI v1.8.3 and later. If you already have the CLI, cube update brings it up to date.
cube login opens your browser so you can approve the session.
2. Find your deployment ID.
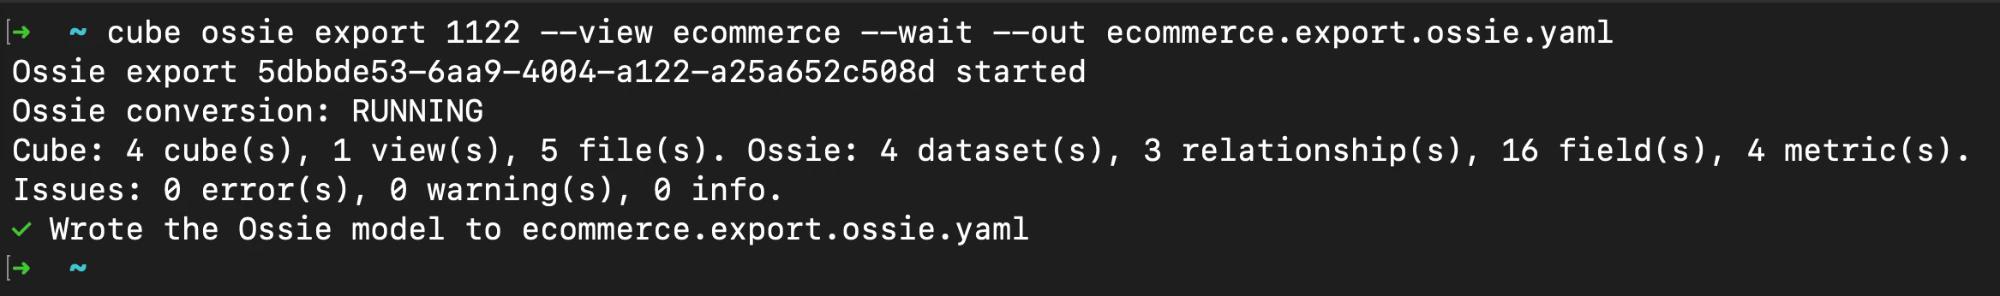
3. Export. This takes the model from your deployment's latest successful build and writes it to ossie.yaml:
The CLI prints how many cubes, views, and metrics it converted, and lists any issues it found along the way.
If you only need one view, add --view. You get exactly what that view exposes, under the view's own names:
To export the files in your local checkout instead of the deployed model, add --from-dir ..
Import works the same way in reverse. From the root of your Cube project, run:
This writes one cube for each Ossie dataset, plus a view on top, into your project. Nothing changes in your deployment until you decide it should: look through the diff, commit it, and deploy it the way you deploy any other model change. If the Ossie model is maintained outside Cube, import --check compares the generated files with what's on disk and fails when they differ, which makes a handy CI check.
If you'd rather script it, the CLI runs on the Platform API, and you can call it directly: POST /api/v1/deployments/{deploymentId}/ossie-conversions starts a conversion, and you poll until the result is ready. You can also run the converter yourself, offline and without Cube Cloud. It's a Python package in converters/cube in the Apache Ossie repo.
How it works
The rest of this post is about what the converter actually does. You don't need it to run an export, but it explains why the output looks the way it does and what the warnings mean.
The mapping
Most of Cube maps onto Ossie directly:
| Cube | Apache Ossie |
|---|---|
| Cube | Dataset |
| Dimension | Field |
| Measure | Metric |
| Join | Relationship |
| View (in a single-view export) | Model name, description, and AI context |
A table becomes a dataset, a join becomes a relationship, a sum measure becomes a SUM(...) expression, and a filtered measure becomes a CASE WHEN. Here's a cube from the converter's tests:
And the Ossie it produces:
You might have noticed that count came out as COUNT(DISTINCT orders.id) rather than COUNT(*). That's deliberate, and it has to do with fan-out.
Fan-out
Take orders joined to users, with many orders per user. In the joined rows, each user shows up once for every order they placed. A SUM(users.ltv) across that join adds up each customer's lifetime value once per order, and the total comes out far too high. Cube handles this at query time: it knows the primary keys and the join types, and it deduplicates rows before aggregating. An Ossie metric is only a SQL expression, so there's nowhere to put that logic, and a tool that joins through the relationship will get a bigger number than Cube does.
The converter can't fix that for other tools, but it doesn't hide it either. Where a safe form exists, it writes that form, which is why orders.count above became COUNT(DISTINCT orders.id). count_distinct, min, and max are already safe, because repeated rows don't change them. Anything else, such as a sum or avg on the "one" side of a join, gets a FANOUT_UNSAFE_METRIC warning instead of being passed through quietly.
Add a sum measure to users:
And the converter tells you:
On a full-model export, the measure still converts, with the warning attached. Add --strict-fanout and the export fails instead. Single-view exports are strict by default, because that file is usually on its way out of Cube.
The spec has no way to mark a metric as non-additive yet, so I opened apache/ossie#290 to add one. It's still open.
A model is a view
An Ossie model has one name, one description, and its own AI context. The closest thing in Cube is a view. Views are what people and agents query, and Cube's agent reads AI context from views and their members. So when you export a single view, its name, description, and AI context become the model's. On import, the converter puts a view on top of the generated cubes and moves the AI context there.
What survives a round trip
Cube has plenty that the spec doesn't: pre-aggregations, segments, hierarchies, access policies, formats. If export simply dropped those, you couldn't get your model back. So the converter keeps them, along with your views, in the Ossie file's custom_extensions under a CUBE key, which is the place Ossie sets aside for vendor-specific data, and import reads them back. For any model that converts, Cube → Ossie → Cube gives you back the model you started with.
Going the other way keeps almost everything too. Ossie details that Cube has no field for, such as exact datatypes, unique keys, or other vendors' extensions, are saved under meta.ossie on the generated cube or member, and they come back on the next export. A couple of things have nowhere to go: AI context on a relationship, since a Cube join has no metadata field, and an is_time flag that contradicts the field's datatype. Those are dropped and reported as DROPPED_NO_CUBE_EQUIVALENT, so you can see exactly what didn't make it.
The CUBE extension only means something to Cube. Another tool reading the same file uses what it understands and ignores the rest.
Single-view export
A full-model export is meant for round trips. A single-view export is meant for files that leave Cube. It contains exactly what the view exposes, under the view's own names, plus any hidden members that a metric depends on. If something can't be represented correctly, like an ambiguous join path or cubes from different data sources, the export fails with an error rather than writing something that's only roughly right.
The report
Every run comes back with a list of issues at three levels. An ERROR means nothing was converted, for example because a cube uses extends. A WARNING means something was dropped or changed, like a skipped Jinja file or a measure that's unsafe under fan-out. An INFO means something was kept in a different form. A geo dimension, for instance, becomes separate latitude and longitude fields and merges back on import.
Where it runs
Conversion runs on Cube's own infrastructure, in a sandbox that only sees your model files. It never touches credentials or warehouse data, and there's no AI involved, so the same input always gives you the same output. For now, only YAML models convert. JavaScript and Jinja files are skipped and show up in the report.
Try it
The Apache Ossie docs cover every CLI flag and the full Platform API flow.
If you're not on Cube yet, request a demo and we'll walk you through Ossie import and export with your own model.